← All projects
Lead Generation
Web Research & Data Operations at Scale
Large-volume company, contact, and candidate research delivered as clean, structured datasets — the day-to-day operations work behind more than one million processed records.
Web researchGoogle SheetsMicrosoft ExcelData validationProcess documentation
Ongoing client work
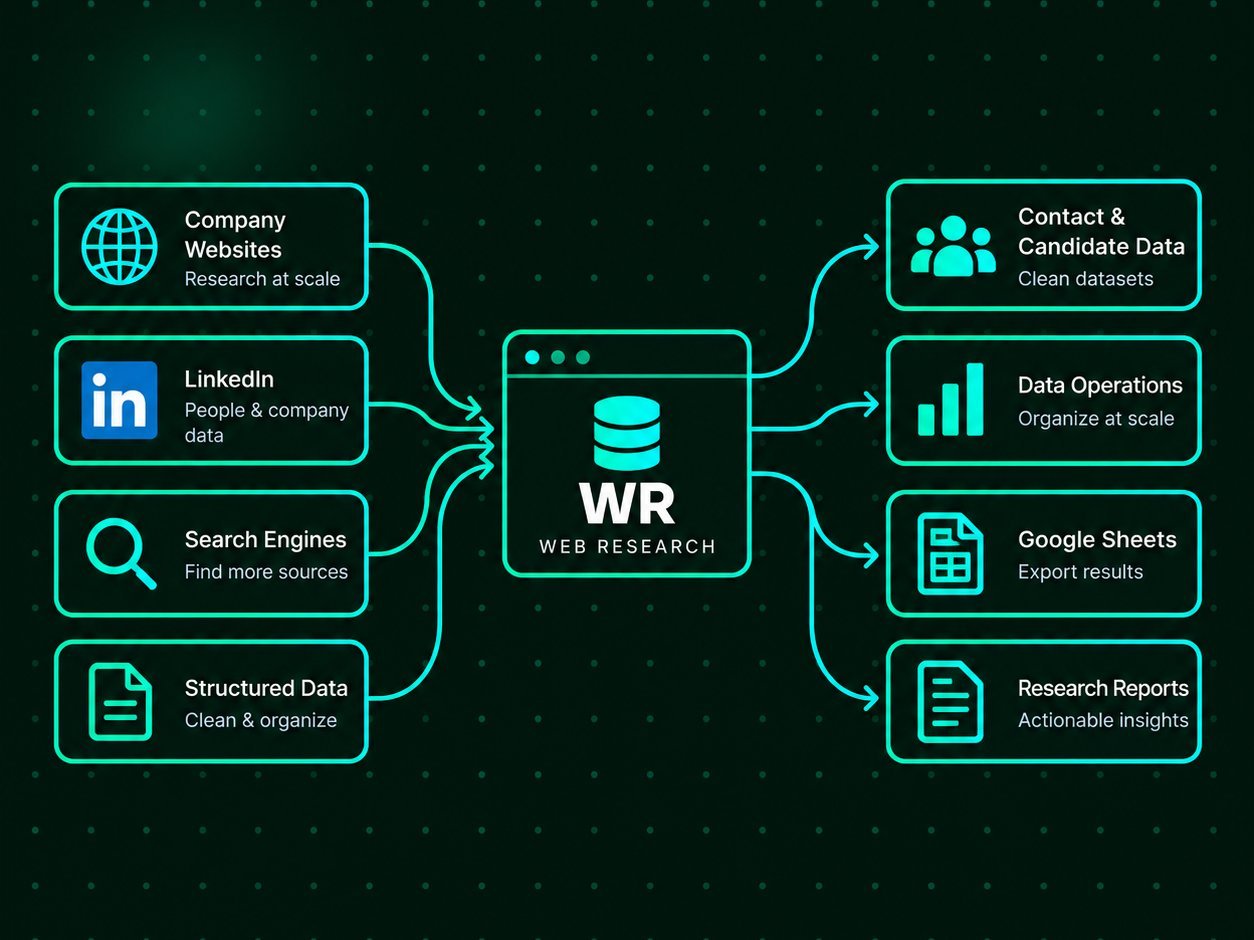
How it flows
- 1Agree the target list and required fields
- 2Research each record from public sources
- 3Validate, de-duplicate, and standardise
- 4Quality-check a sample before delivery
- 5Deliver in the client's format
What the work looks like
A client sends a list of companies, or a description of the companies they want. The team researches each one — website, size, location, key people, contact details — and returns a spreadsheet where every column is filled the same way, every time.
What makes it reliable
- Definitions first — each field has a written rule (for example, how to record a phone number or which title counts as a decision-maker).
- Validation — emails and phones are checked; dates and names are standardised.
- De-duplication — across the new batch and against what the client already has.
- Quality sampling — a share of every batch is re-checked by a second person before it is delivered.
Why it matters here
Most of the automations and tools on this site — the Excel cleaning pipeline, the CRM, the scrapers — exist because I did this work by hand first and knew exactly which steps were worth automating.